I got DLSS 5 running in NieR:Automata at 4K over the weekend, then started testing Qwen on game footage as a hypothetical DLSS 6 standin. Diffused frames look great, but temporal coherency and kernel optimization still prevent SoTA models from running in realtime. In short, the 100 million parameter ViT model Nvidia has shipped is perfectly sized for the task.
The other projects here have AI writing programs that build structures in Minecraft, and editing Pokémon's source to rebuild the game around a request. I think we could start connecting these pieces over the next year: changing the visuals, building the world, and modifying the rules while you play. That's what I want from a 'DLSS 6'.
NieR:Automata · Resistance Camp · captured at 3840 × 2160
NieR:Automata with DLSS 5
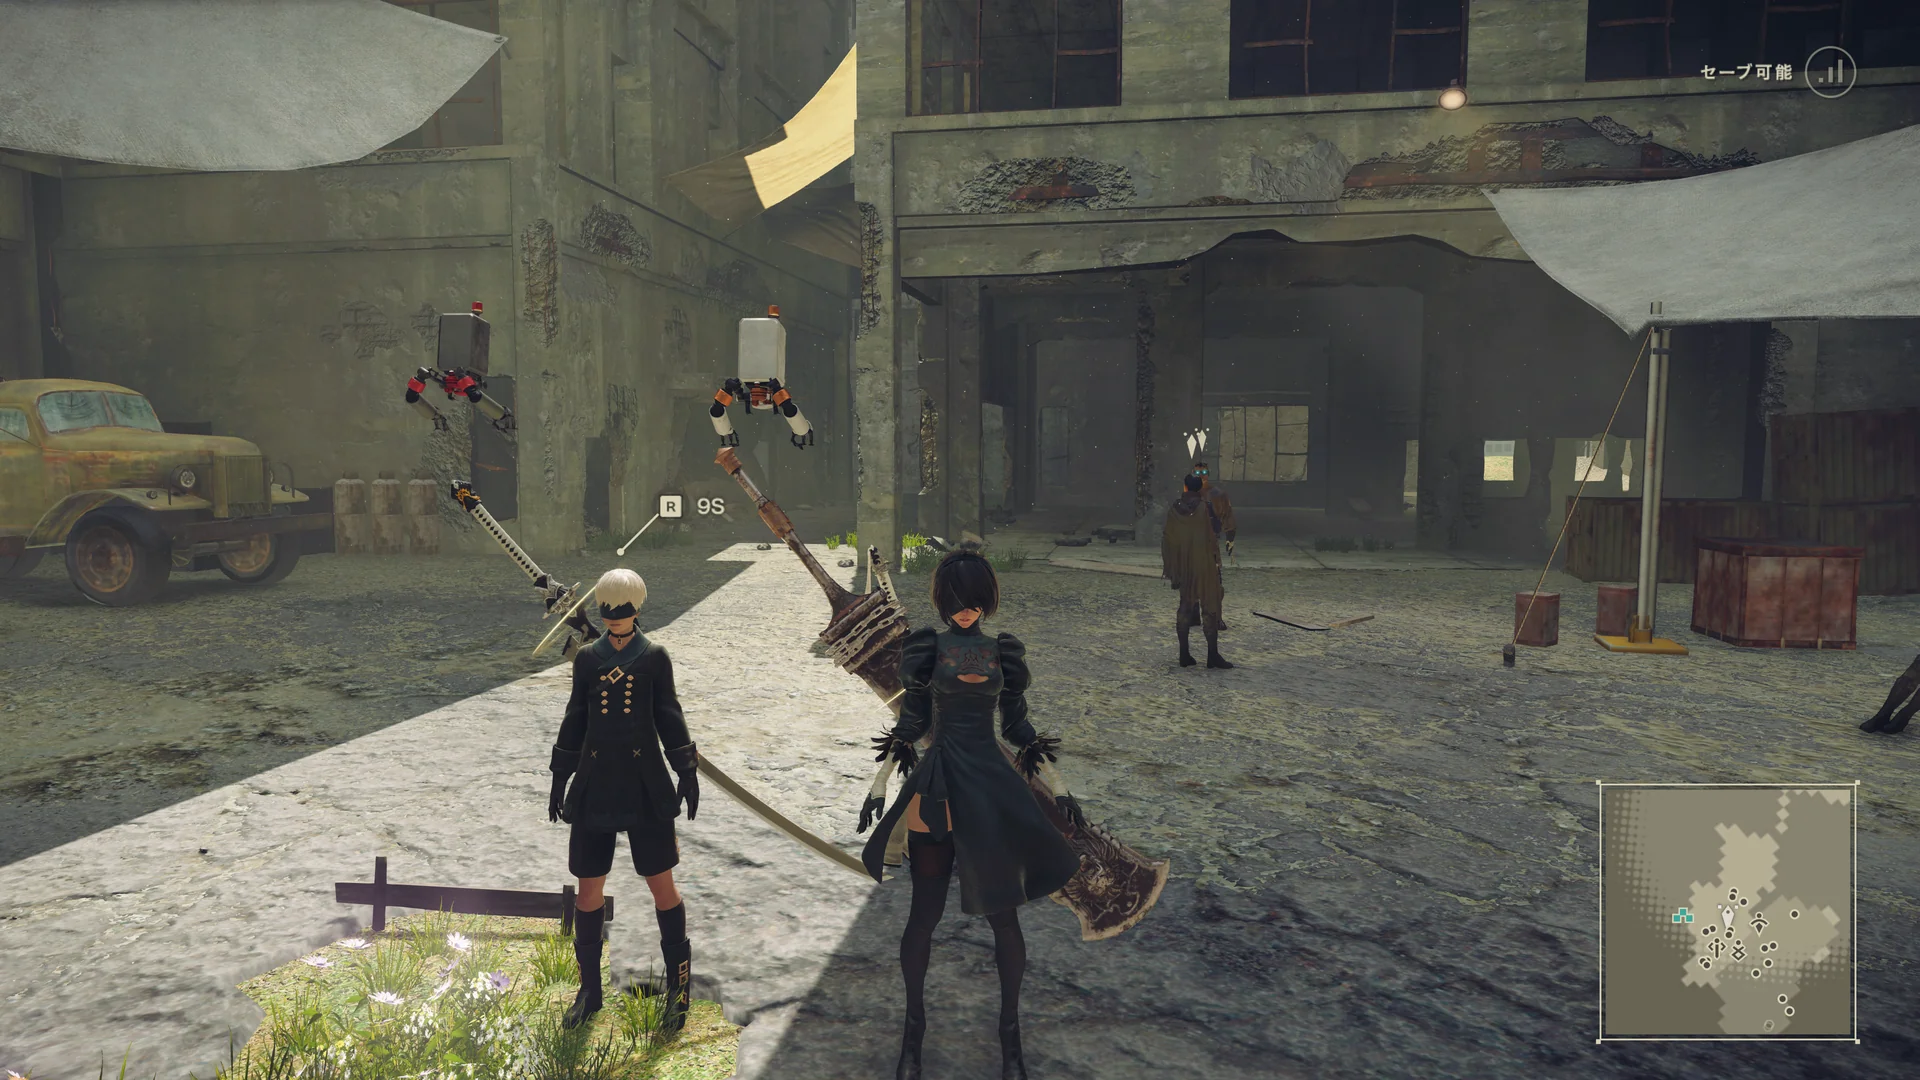
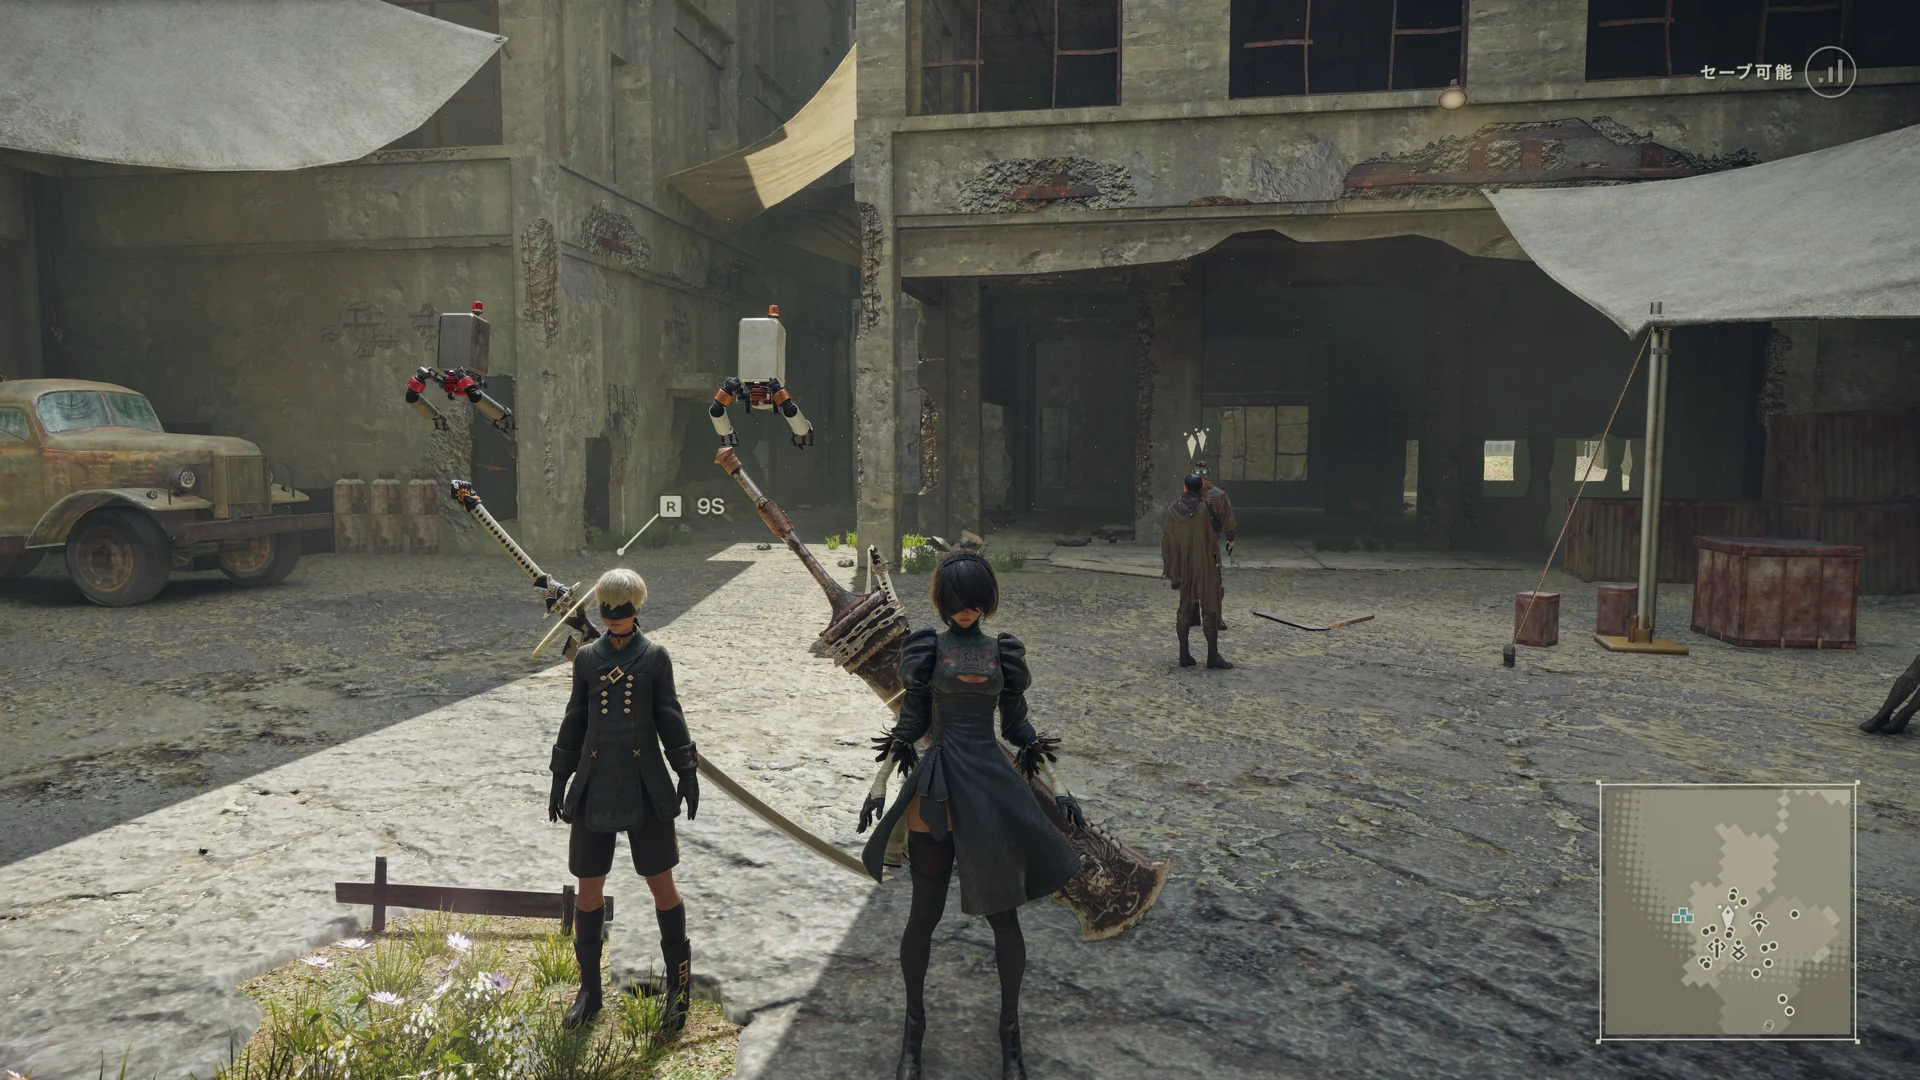
Comparison image files. Use the links below to inspect the supplied assets.
Pressing F9 toggles it during gameplay. The first result looked good, so we added live controls and tried running multiple passes. That exposed artifacts and inconsistent comparisons, which led us to investigate the model's temporal state.
- The integration runs. A reviewed live session recorded 5,280 successful 4K NR submissions, with no recorded NR error or timeout. It has a toggle, a status badge, and live artist controls. This is bespoke and doesn't require third party libraries.
- More inference did not guarantee a better image. Repeated passes amplified changes and distortion. Inspecting the model and isolating its temporal state explained why apparently identical inputs could behave differently.
- There are also working demos beyond rendering: AI-authored Minecraft buildings and an agent that rebuilds Pokémon Emerald to change its behavior suggest we are close to games that write their own worlds.
- This is an experimental integration. Motion is synthetic zero, depth interpretation is unverified, and the game's HUD goes through the model. The newer Qwen work produces some beautiful stills, but a convincing sequence and a real-time replacement remain unfinished in this weekend project.
The familiar DLSS question is how to reconstruct an expensive image from a cheaper render via some sort of interpolation. DLSS 5 Neural Rendering adds another question: what appearance could a learned model contribute that the renderer never explicitly simulated?
NVIDIA describes a one-step, pixel-space diffusion model, conditioned on the current rendered image, engine motion, temporal state, and artistic controls. Its report describes a transformer of approximately 154 million parameters, using mostly FP8 arithmetic with selected FP16 matrix multiplications. This is an additional rendering stage, independent of Super Resolution and Frame Generation. NVIDIA research overview, technical report, §2.6.
That distinction matters for an older game. NieR already has a strong visual identity but comes from an era of pre RTX graphics. Adding detail is easy to admire in a still; keeping its silhouettes, UI, lighting choices, and motion intact is a much higher bar. My goal was to investigate that boundary.
The public Streamline SDK knew the name of the feature: kFeatureDLSS_NR = 1004. The package I downloaded did not contain the runtime or its integration header.
I checked several official routes. This is a record of those particular packages:
| Inspected route | What was there | What I did not find |
|---|---|---|
| Streamline 2.14.1 | The feature ID and changelog references | NR header, runtime, or integration guide |
| UE 5.8 DLSS plugin 8.8.0 | An NR guide describing styles, masks, and controls | The NR implementation or runtime |
| RTX Kit 2026.3 catalog | DLSS and Streamline entries | A public NR component; the detailed manifest required login |
| Driver's NGX updater | A successful updater exit | A downloaded NR package |
NVIDIA said NBA 2K27 shipped the feature, and its technology description said inference ran locally. An installed game needed executable model code somewhere, so naturally I looked there.
In its data\streamline directory were nvngx_dlssnr.dll 310.8.0.0 and sl.dlss_nr.dll 2.13.0.0, signed by NVIDIA Corporation. I copied the required runtime modules into a private project directory, pinned their hashes, and verified signatures before loading them. The installed game was read only. No NVIDIA binary was patched, and the integration does not dispatch into hard-coded disassembly addresses.
There is an important distinction between having a runtime that can execute inference and having an SDK with a supported training interface. Finding the former did not provide the latter. This article includes measurements and images, not NVIDIA runtime files or weights. I have a breakdown of the architecture and model on huggingface.
The pinned NR adapter advertised D3D12 and Vulkan. Its runtime had an explicit D3D11-unsupported diagnostic, despite exporting functions with D3D11 in their names. A plausible-looking export was not evidence that the path worked.
The solution was a small dxgi.dll proxy next to NieR's executable. It forwards the normal graphics calls and intercepts presentation. The game remains on D3D11; a second device on the same physical GPU runs NR through D3D12.
Inside the NieR integration
One frame across two graphics APIs
One GPU. Two devices. Shared textures and fences connect them.Select a stage to inspect its inputs, handoff and limits.
Stage 1 of 5 · D3D11
Start with the frame the game actually rendered
The proxy intercepts Present and borrows the current back buffer on the game’s immediate-context thread. It does not replace the game’s renderer.
Rendered color → the bridge
Input and state limits
The game’s HUD is already in this image. Depth is an observed full-size D24S8 candidate; the game’s camera and depth interpretation remain unverified.
Stage 2 of 5 · Shared resources
Share texture storage, then order the work
A D3D12 device is created on the game’s own DXGI adapter. Shared texture handles expose the resources to D3D11; a shared fence makes the D3D12 queue wait for the input copy.
D3D11 signals ready → D3D12 waits
Input and state limits
The NR color input is RGBA8. SDR RGB10A2 passes through a 10→8→10-bit conversion; HDR is rejected. Frame transfer stays on the GPU.
Stage 3 of 5 · D3D12
Evaluate the pinned NVIDIA model
The integration tags color, depth, motion and output resources, then records NR through Streamline’s feature API. The NVIDIA DLLs are signature-checked, hash-pinned and unmodified.
Input resources → NR output texture
Input and state limits
Motion vectors are synthetic zero. The requested per-frame reset does not clear history. This diagram shows the original NieR Streamline path.
Stage 4 of 5 · Shared resources
Return the result only after NR completes
D3D12 signals the completion fence. D3D11 waits on that shared fence and copies the enhanced color back into the game’s back buffer, with the caller’s graphics state restored.
D3D12 signals done → D3D11 waits
Input and state limits
Shared fences order GPU work; submission alone is not a completion-time measurement. CPU readback is reserved for separate diagnostic captures.
Stage 5 of 5 · D3D11
Draw our status badge, then present
The small NR status overlay is drawn after enhancement, before the original Present call. F9 controls the integration; disabling it retires the pipeline and releases its resources.
Enhanced frame + status badge → display
Input and state limits
Our badge stays out of the model. The game’s own HUD does not. The bridge proves that inference runs; it does not establish correct engine guides or visual quality.
Diagram of resource flow, not a frame-time chart.
The expensive mistake here would be to confuse “submitted” with “finished.” Shared resources need the right ownership, state transitions, and fences in both directions. The game cannot sample an output merely because the CPU has finished calling the inference function.
The missing header was a separate problem. Read-only inspection of the pinned adapter recovered a 72-byte, version-3 options object. It contains the artist controls and mode fields. The integration obtains its setter through Streamline's public slGetFeatureFunction API. The recovered declaration describes this binary; it is not an official, version-independent NR SDK.
I tested the integration in stages:
- Load it outside the game. Initialize Streamline, query support, bind a D3D12 device, and verify the feature is loaded.
- Prove the bridge can copy. An identity pass must return the input exactly before a model is allowed to change it.
- Run a known scene. A synthetic room with analytic depth and zero motion produced a changed, nonblank image. That established execution, not realism.
- Capture both sides in NieR. Read back the input and output from the GPU, then run continuously. The reviewed session reached 5,280 successful submissions at 3840 × 2160.
One particularly unhelpful bug was in the instrumentation: live D3D11 context dispatch entries changed during state swaps, so a hook installed once could stop observing depth after the first NR frame. Rechecking the hooks around presentation restored observation. The missing depth observations were a hook problem, not evidence that the game had stopped using depth.
The live panel exposes intensity, tone, structure, Style 0/1/2, and skin-mask controls. The style IDs retain NVIDIA's numbering rather than invented names. F9 is the immediate on/off comparison; the separate pass-count and history controls are my additions.
Once a single pass worked, I added a setting to run the same model two to five times on each frame.
At five full-strength passes, the gameplay captures showed bright rims around hair, exaggerated surface texture, and HUD lettering that looked embossed. Those captures also changed style, camera position, and pose, so they could not isolate the effect of pass count. They were a reason to build a controlled experiment.
Repeating this model is not the same as advancing a diffusion sampler. Each invocation is a complete one-step renderer. Pass two sees the appearance invented by pass one, while its geometric guides still describe the original game frame. There is no established training objective that makes this feedback chain converge toward a better image.
I tried reducing the intensity of the extra passes:
pass_intensity[k] = selected_intensity × extra_strength^k

extra_strength = 0.25
five passes   = 1, 0.25, 0.0625, 0.015625, 0.00390625
After isolating state between evaluations, the control did what it was meant to do:
The menu gained two independent switches: Weaken extra passes and Separate pass histories. The latter keeps one persistent feature for each logical pass. In the tested 720p and 4K sequences, that made each first-pass result exactly match its corresponding single-pass reference despite the intervening passes.
Neither switch recovers correct motion or removes the game's HUD. They address specific failure modes. In particular, “five passes” is my experiment, not an NVIDIA quality preset.
The first attenuation test did not make sense. A later case that performed only one evaluation differed from the original single-pass baseline. The input had been restored. A reset had been requested. What else was changing?
Waiting for GPU completion after every pass did not help: all 14 comparable final images were byte-identical to the queued run. Replaying the sequence in a fresh process reproduced it. That made a random synchronization failure less convincing and persistent model state more interesting.
The adapter's argument conversion supplied the explanation. In the pinned sl.dlss_nr.dll, it wrote a literal false value into the native reset field instead of forwarding the application's request. Feature creation initialized history; the per-frame flag I was setting did not clear it.
The log records the distinction:
resetRequested=true resetRequestHonored=falseI checked the implication through a separate, direct NGX harness using the same native runtime. It created one feature and kept it alive for eight evaluations. Feed the generated result back in, restore the original input, and compare against the baseline:
| Experiment | RGB difference from baseline |
|---|---|
| Repeat original input with native reset | 0 — exact |
| Restore original input after feedback, reset off | 2.7897 |
| Restore original input after feedback, native reset on | 0 — exact |
The native reset worked without recreating the feature. This is evidence about the tested adapter and runtime, not a claim that every DLSS integration drops resets.
The input to a temporal renderer includes its history. Two identical color buffers are not equivalent test cases if the hidden state differs. A pass-count experiment without state isolation was partly measuring the order in which I ran the experiment.
Getting the model to execute raised the next question: how much of it could we understand well enough to reproduce?
Read-only analysis of this runtime identified 71 numbered blocks, a hierarchical Swin-style encoder and decoder with skip connections around a 1,024-channel ViT core. The 153 packed weight records decoded into 851 tensors and repacked exactly, with 2,394 bytes still uninterpreted. That checks the recovered representation. It does not establish a working forward pass.
We also traced the temporal inputs and outputs. The preprocessing path assembles current RGB, reprojected previous RGB, procedural noise, and artistic controls into a 16-channel input. The output predicts an RGB residual and a learned history-blending gate. At an algebraic level, the recovered final-color path behaves like this:
candidate = clamp(current + predicted_residual / 4)
temporal  = blend(candidate, warped_history, learned_gate)
displayed = blend(current, temporal, artist_intensity)
history   = temporal
This is an explanation of the recovered data flow, not a numerically interchangeable implementation. Fused arithmetic, rounding, masks, and history-validity conditions still matter.
In this path, the history can be written before the final intensity blend. Turning down the displayed effect does not necessarily turn down the image remembered by the model. It is another reason an ordinary image filter is a poor model of the system.
For numerical validation, I picked one bounded target: the ViT feed-forward expansion. A PyTorch reference matched NVIDIA's native FP8 kernel byte for byte across 4,751,360 output values, in 24 comparisons spanning two weight blocks. Matching the matrix multiplication alone was insufficient; reproducing the half-precision accumulation and fused activation rounding boundaries mattered.
That result establishes one operator on the tested hardware and inputs. Full-network inference, frame equivalence, and fine-tuning remain unfinished. A decoded checkpoint and a differentiable approximation are useful pieces, but they are not a trainable replacement renderer.
The machine was an RTX 5090 with 32 GB of VRAM, driver 616.92. NieR's Steam build was 7020666.
The standalone harness measured:
Standalone bridge harness · RTX 5090 · 3840 × 2160
NR inference time at 4K
A 60 FPS game has 16.67 ms for the entire frame. The harness measurements include the bridge's conversion and synchronization, but game rendering and presentation remain outside that budget. Likewise, roughly 60 successful submissions per second in a log is not a controlled end-to-end performance benchmark.
At max native settings without NR, I would see the RTX 5090 running around 20% utilization. Turning on single pass NR pushed the GPU towards 90%. Not seeing it go to a full 99/100 made me realize there was a bit of headroom we could exploit in the future.
The inputs constrain what we can say about image quality too:
| Integration data | What this NieR prototype supplies |
|---|---|
| Current scene color | Final back buffer, converted to RGBA8; game HUD included |
| Motion | Synthetic zero vectors |
| Depth | A real D24S8 candidate selected from bindings; projection and inversion unverified |
| Camera information | Fallback constants; actual game matrices not recovered |
| History reset | Requested through Streamline, but dropped by this adapter |
| Color convention | SDR; HDR was disabled for these runs |
Those are integration limitations, not a test of NVIDIA's best possible output. Nor does listing a supplied buffer establish that every native code path consumes it. The support interface asks for depth; the particular native manager path inspected did not establish the expected depth use.
The immediate engineering target is one trustworthy pass: verified motion and depth semantics, controlled history, and a clean separation between scene color and HUD. Repeating an uncertain pass cannot supply those missing contracts.
Next, we tried Qwen-Image-2.1, which has a 7B image-generation backbone. This was supposed to be the no-compromises, 'what if we solved the technical challenges' upgrade from Nvidia's 100M NR. The goal was to use its larger model for rendering, with low precision, fused kernels, sparse updates, and temporal reuse to reduce the cost.
The optimizations included combined Q/K/V projections, compiled pointwise operations, native NVFP4 matrix multiplications, and shared activation packing for the two SwiGLU input projections. Some improvements were byte-exact relative to the chosen quantized baseline. That did not make NVFP4 equivalent to BF16, or make a short token benchmark equivalent to a rendered frame. As with many ViT's, there was a small but noticable dip in performance from BF16 to NVFP4.
For a matched native-4K still-image comparison, we measured:
| Qwen, 40 steps, same image and settings | Pipeline wall time |
|---|---|
| BF16, fused | 579.47 s |
| Selective NVFP4, fused | 531.01 s |
Both used a tiled VAE and produced exact 3840 × 2160 crops without output resizing. These were native-size generations, not untiled, uncompromised reference runs. NVFP4 reduced this run's wall time by 8.36%. It did not close the gap to a 33.33 ms frame budget.
We also tested selective spatial updates: update selected spatial tokens and carry context elsewhere. A resident 7B transformer's small-token benchmarks could reach tens of milliseconds. The first untrained sparse rollouts, however, lost image fidelity. Fast execution of the selected tensors did not establish that they contained enough information to render the frame.
One VAE memory optimization helped the offline run. The Qwen VAE retained temporal caches even on the single-image path. Removing caches unused by the tested one-frame computation preserved outputs in bounded parity checks. That made larger untiled image operations more practical. It still did not make the complete native-4K decode fit the chosen 24 GiB allocation cap.
For an offline Ghostwire: Tokyo clip, I lowered the working resolution to 2048 × 1152 and scheduled about eight Qwen updates per source second, with 40 steps per keyframe. The plan was to transport the appearance changes between anchors using optical flow estimated from original game frames, then composite onto the original 4K sequence. That would be 4K reconstruction from lower-resolution edits, not a native-4K Qwen generation for every frame. This implemention was not perfect and I hope to come back to it in the future given it's intial promise.
Some of the Shibuya frames look beautiful after Qwen processes them. Here is the original frame next to the 40-step output:
Ghostwire: Tokyo · Shibuya
Qwen 40 steps
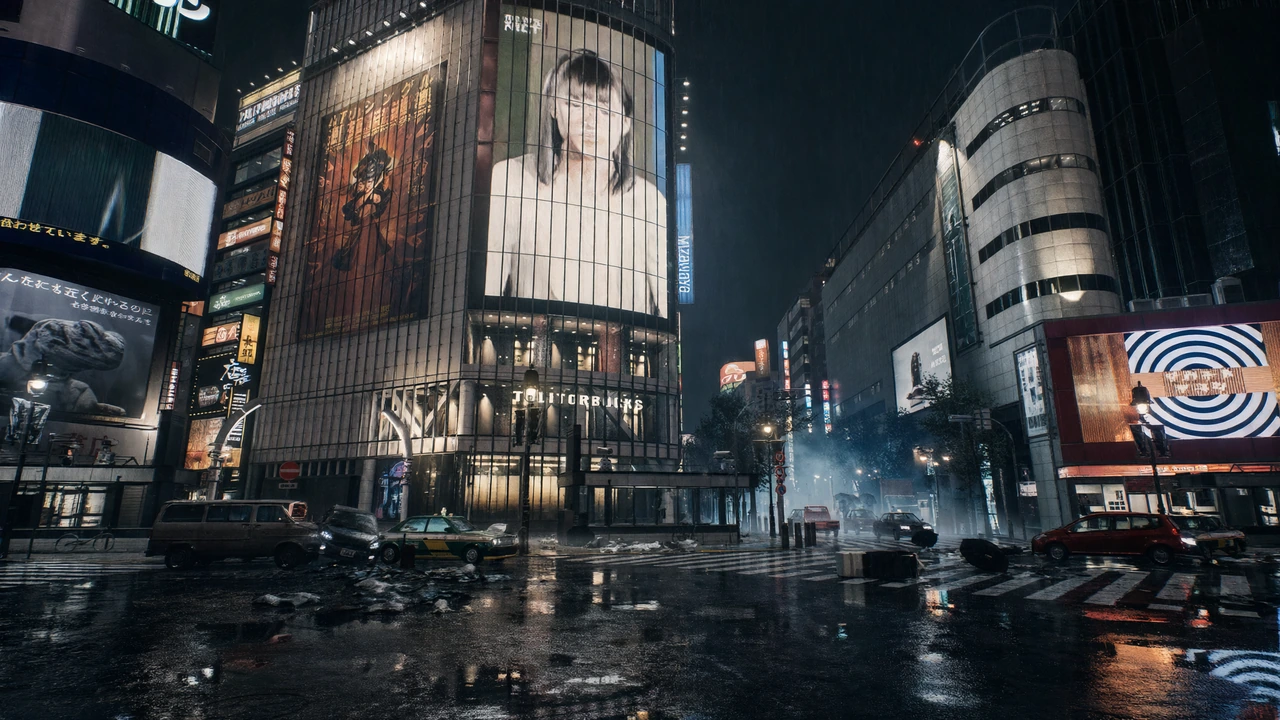
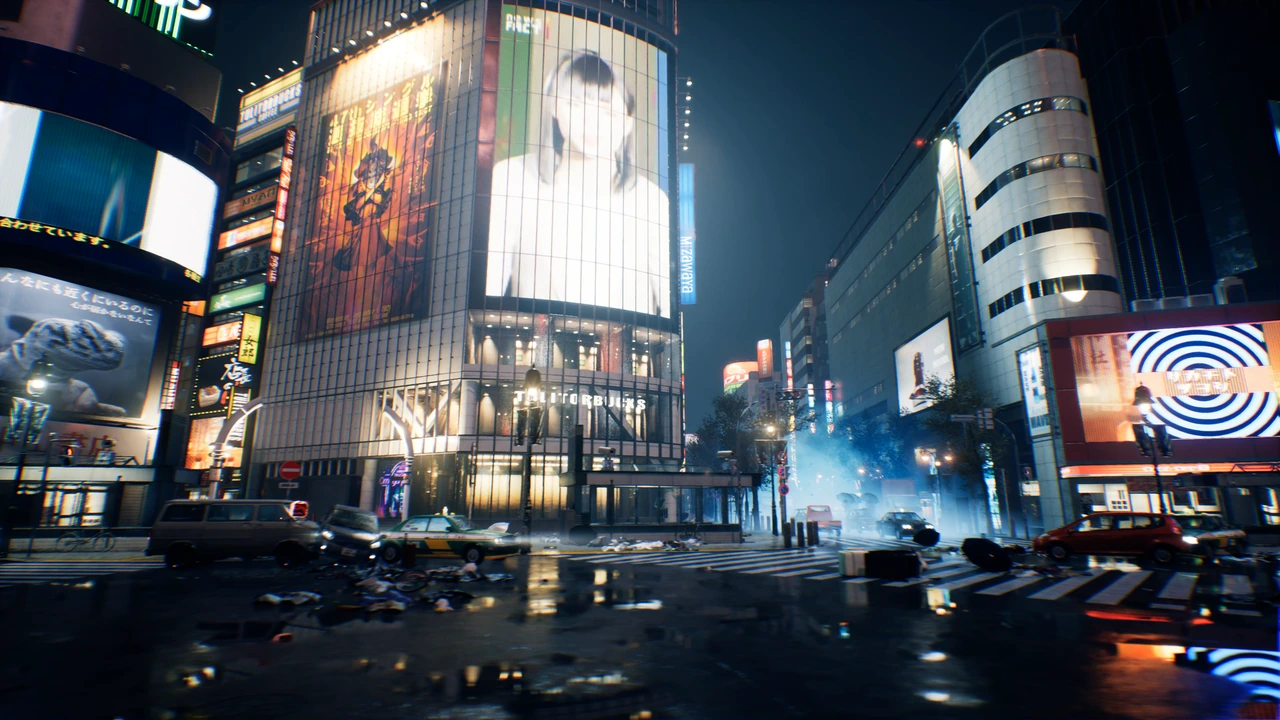
Loading matched pairs…
Independent 40-step image edits. Preview pairs use matching framing and display RGB opaquely; use Inspect images for the larger supplied assets. Playback waits for both images and starts only when requested.
Open the comparison separately → Drag the comparison divider, then scrub through all 71 completed frames at their source timestamps.
The sequence clearly still needs work.
I paused at 71 of 297 scheduled keyframes because the generation did not look right.
We have useful still-image results, but no working real-time Qwen renderer yet. The remaining work is to preserve the scene across frames while reducing how much of the model runs on each update.
Next I want to connect neural rendering with systems that can change game behavior. A player could ask an NPC to accompany them, introduce a new interaction with an object, or change how an encounter works. The system would need to generate behavior that actually runs in the game and persists after the camera moves away.
That would require access to game state and an engine interface for applying changes. One approach would generate small scripts or behavior graphs, validate them, then load them at a safe point in the simulation. The engine would still track collisions, inventory, quest progress, and saved state. Code generation could run when a change is requested, while rendering continues on its own frame budget.
Making a wall look like a doorway would only change the image. Making it usable would also require updating collision, navigation, and the destination on the other side. That's the kind of modification I mean by rewriting the game during play.
The NieR/Qwen renderer handles appearance. Separate experiments later in this post generate buildings and modify a game's source. The remaining challenge is to connect those capabilities without losing control over the world or the game's state.
First, a short sequence with camera motion, independently moving objects, and newly revealed surfaces. Preserve the original frames and compare enhancement at matched strength. Measure motion-compensated instability, edge displacement, HUD changes, and actual GPU frame time separately.
Second, improve one component at a time. Establish a faithful one-pass reference before adding recursive passes. Establish a useful sparse update before quoting its latency. Establish a controlled image-editing result before leaving a long video job overnight.
The next version needs correct motion, reliable history, and tighter control over what changes from the original frame. Those are the requirements we need to test alongside model quality and inference speed.
There is another project that takes this idea in a different direction. An agent takes a real building's footprint, surveyed heights, and reference images, then writes a program that builds it from Minecraft blocks. The program produces geometry we can save, render, inspect, and check. Floors, stairs, doors, rooms, and furniture become part of the world.
This is the kind of persistent representation I want alongside neural rendering. Minecraft already provides collision, weather, lighting, and interactions with its blocks. The generated structures can use those systems. (Also, voxels are notoriously cheap to compute.)
World construction
The recording is a placement demonstration, not a measurement of normal build speed. The next examples show how we check individual buildings against their inputs.
The Peninsula Tokyo
The reference package includes the real footprint, an LOD2 roof-height map, an aerial image, and facade textures. Opus used the expanded package to write a building program with a podium, entrance canopy, rooftop detailing, helipad, and furnished interiors.
The Opus build scored 0.9967 on our construction verifier. Separately, 5,211 of 5,216 known roof columns were within two blocks of the supplied height map. At this project's scale of 1.5 blocks per metre, that tolerance is about 1.33 metres. The interiors are generated designs, not recovered survey data.
The plainer DeepSeek V4.1 Flash result actually scored slightly higher: 0.9986. The verifier checks things such as entrances, connected spaces, floors, lighting, and furnishings. Its score does not measure photographic resemblance. A high score and a convincing reconstruction are different requirements.
Every checked program version was saved. Here are the 25 saved checks replayed in order:
Peninsula program revisions
Inspect the larger exterior render · Inspect the cutaway. Both are fresh 2284 × 3250 renders of the saved final geometry. The Opus examples are reserved for evaluation and are excluded from training.
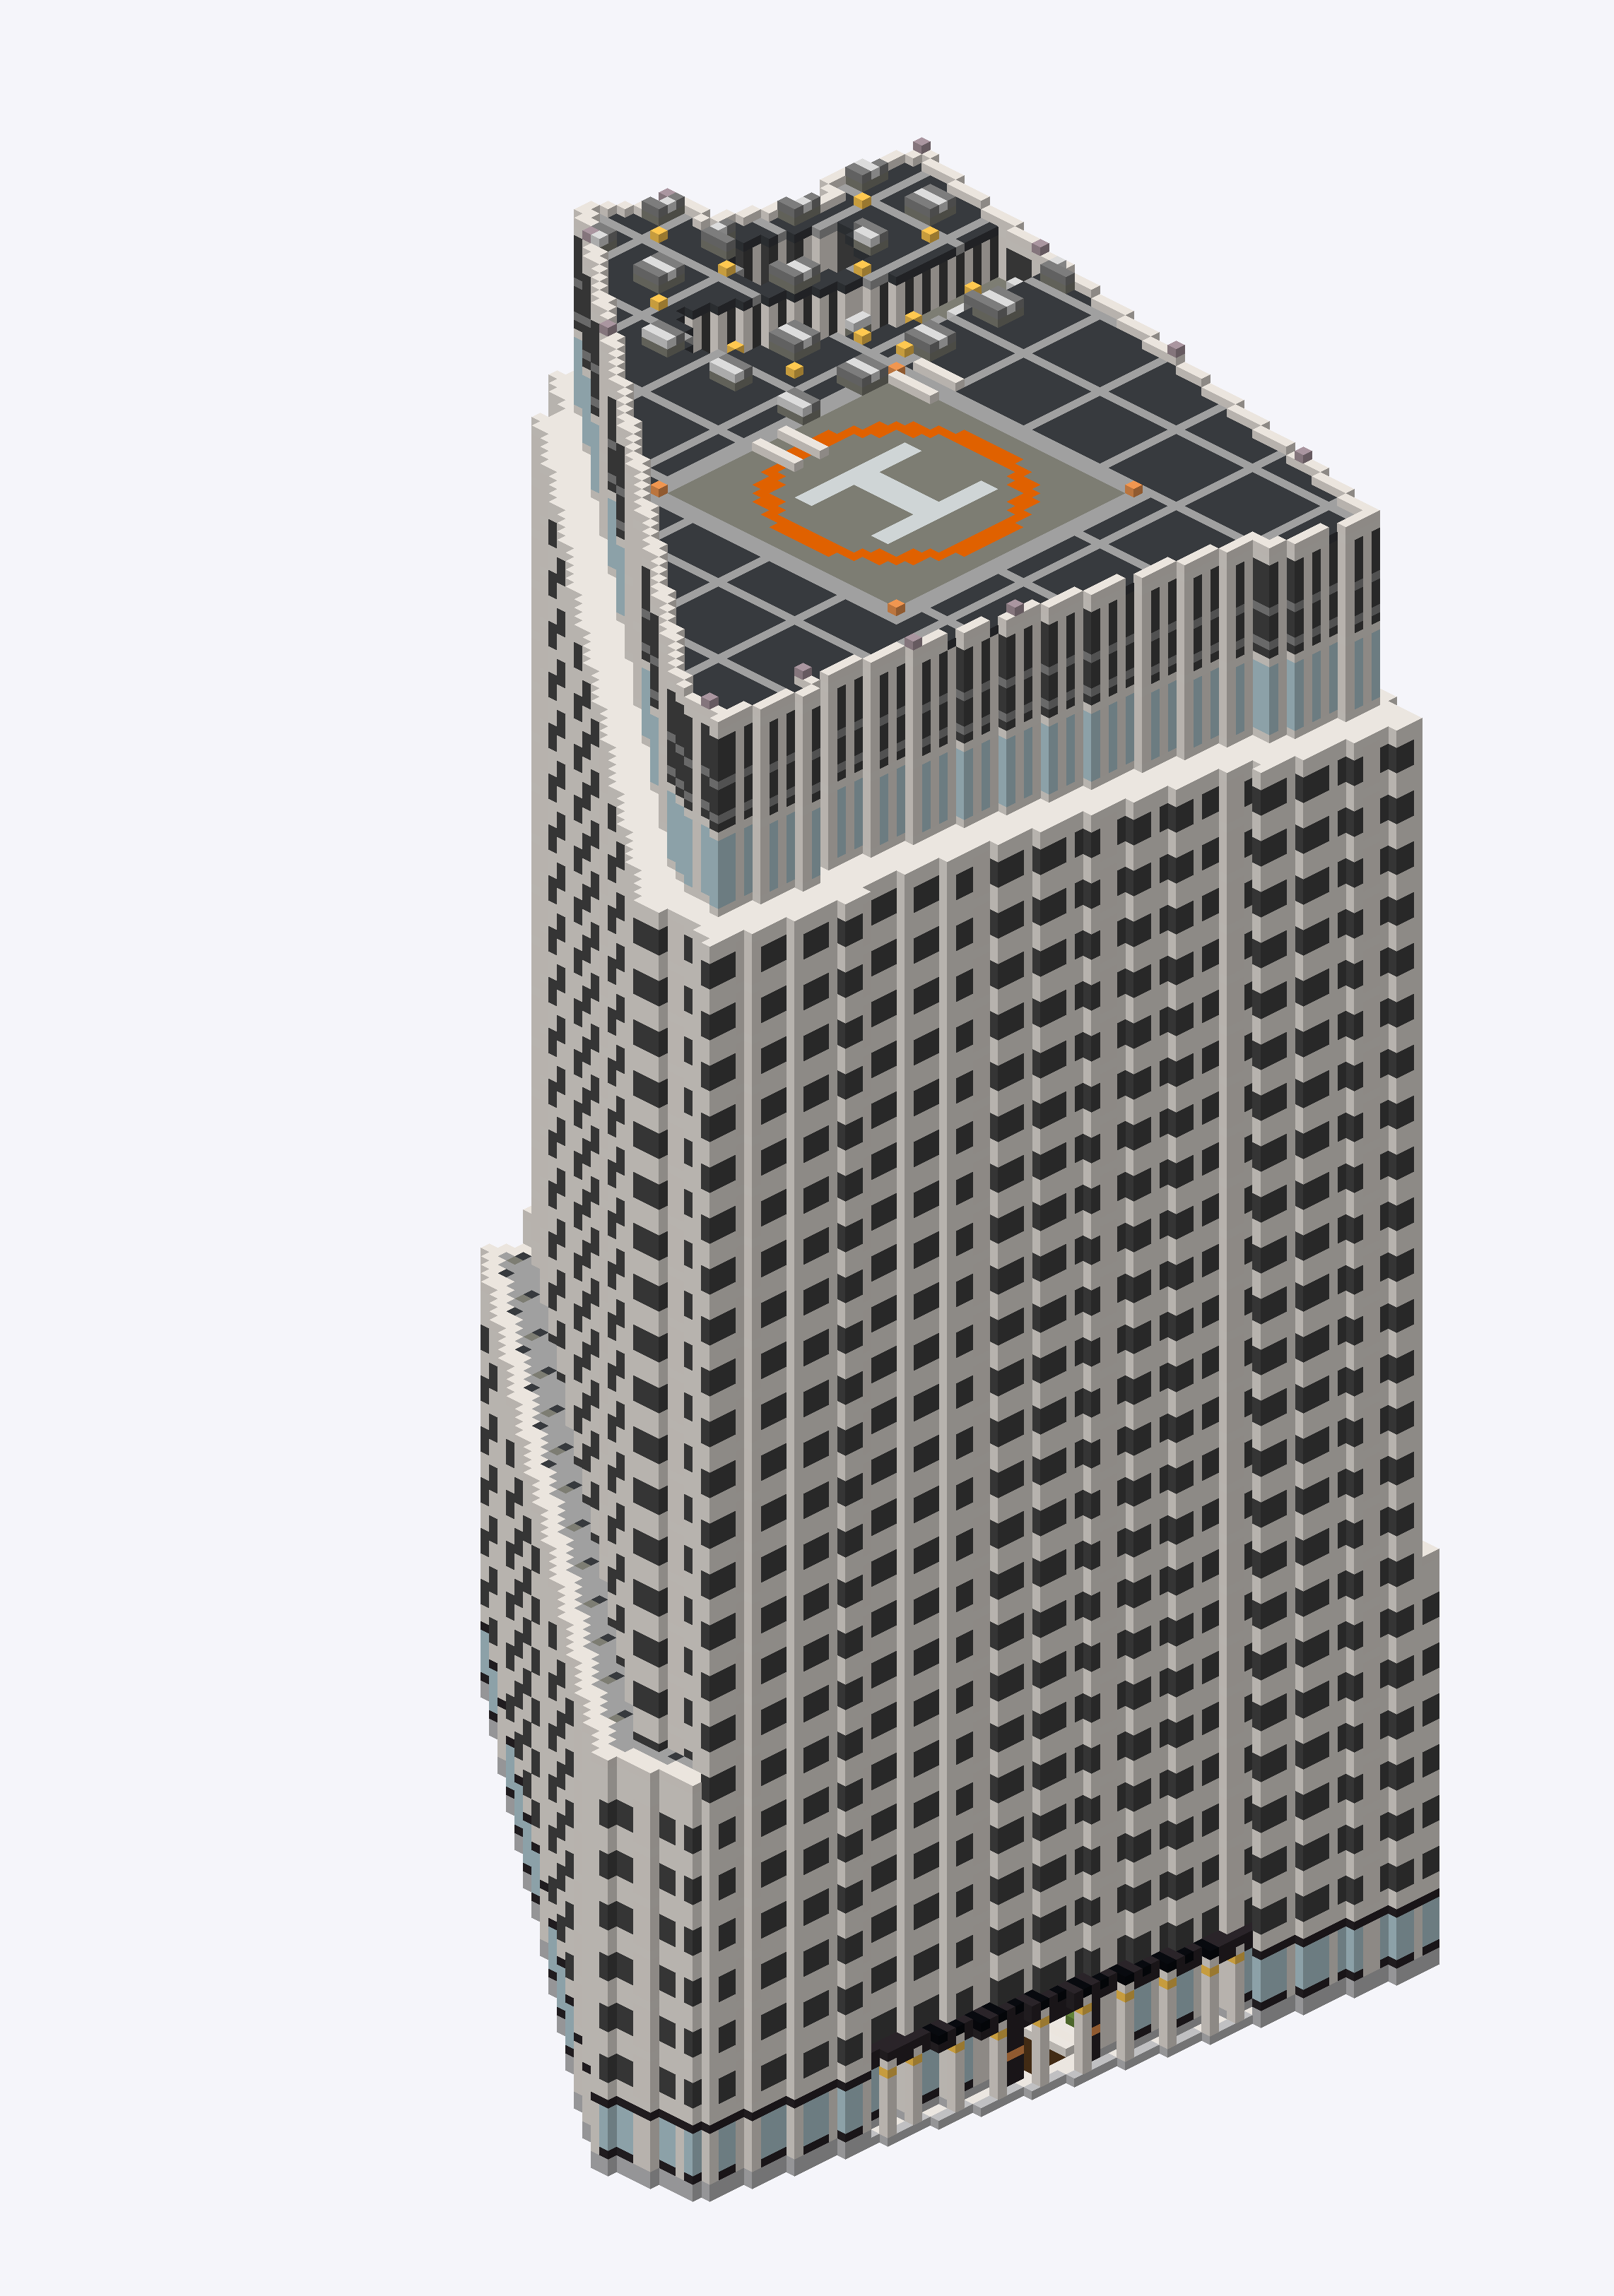
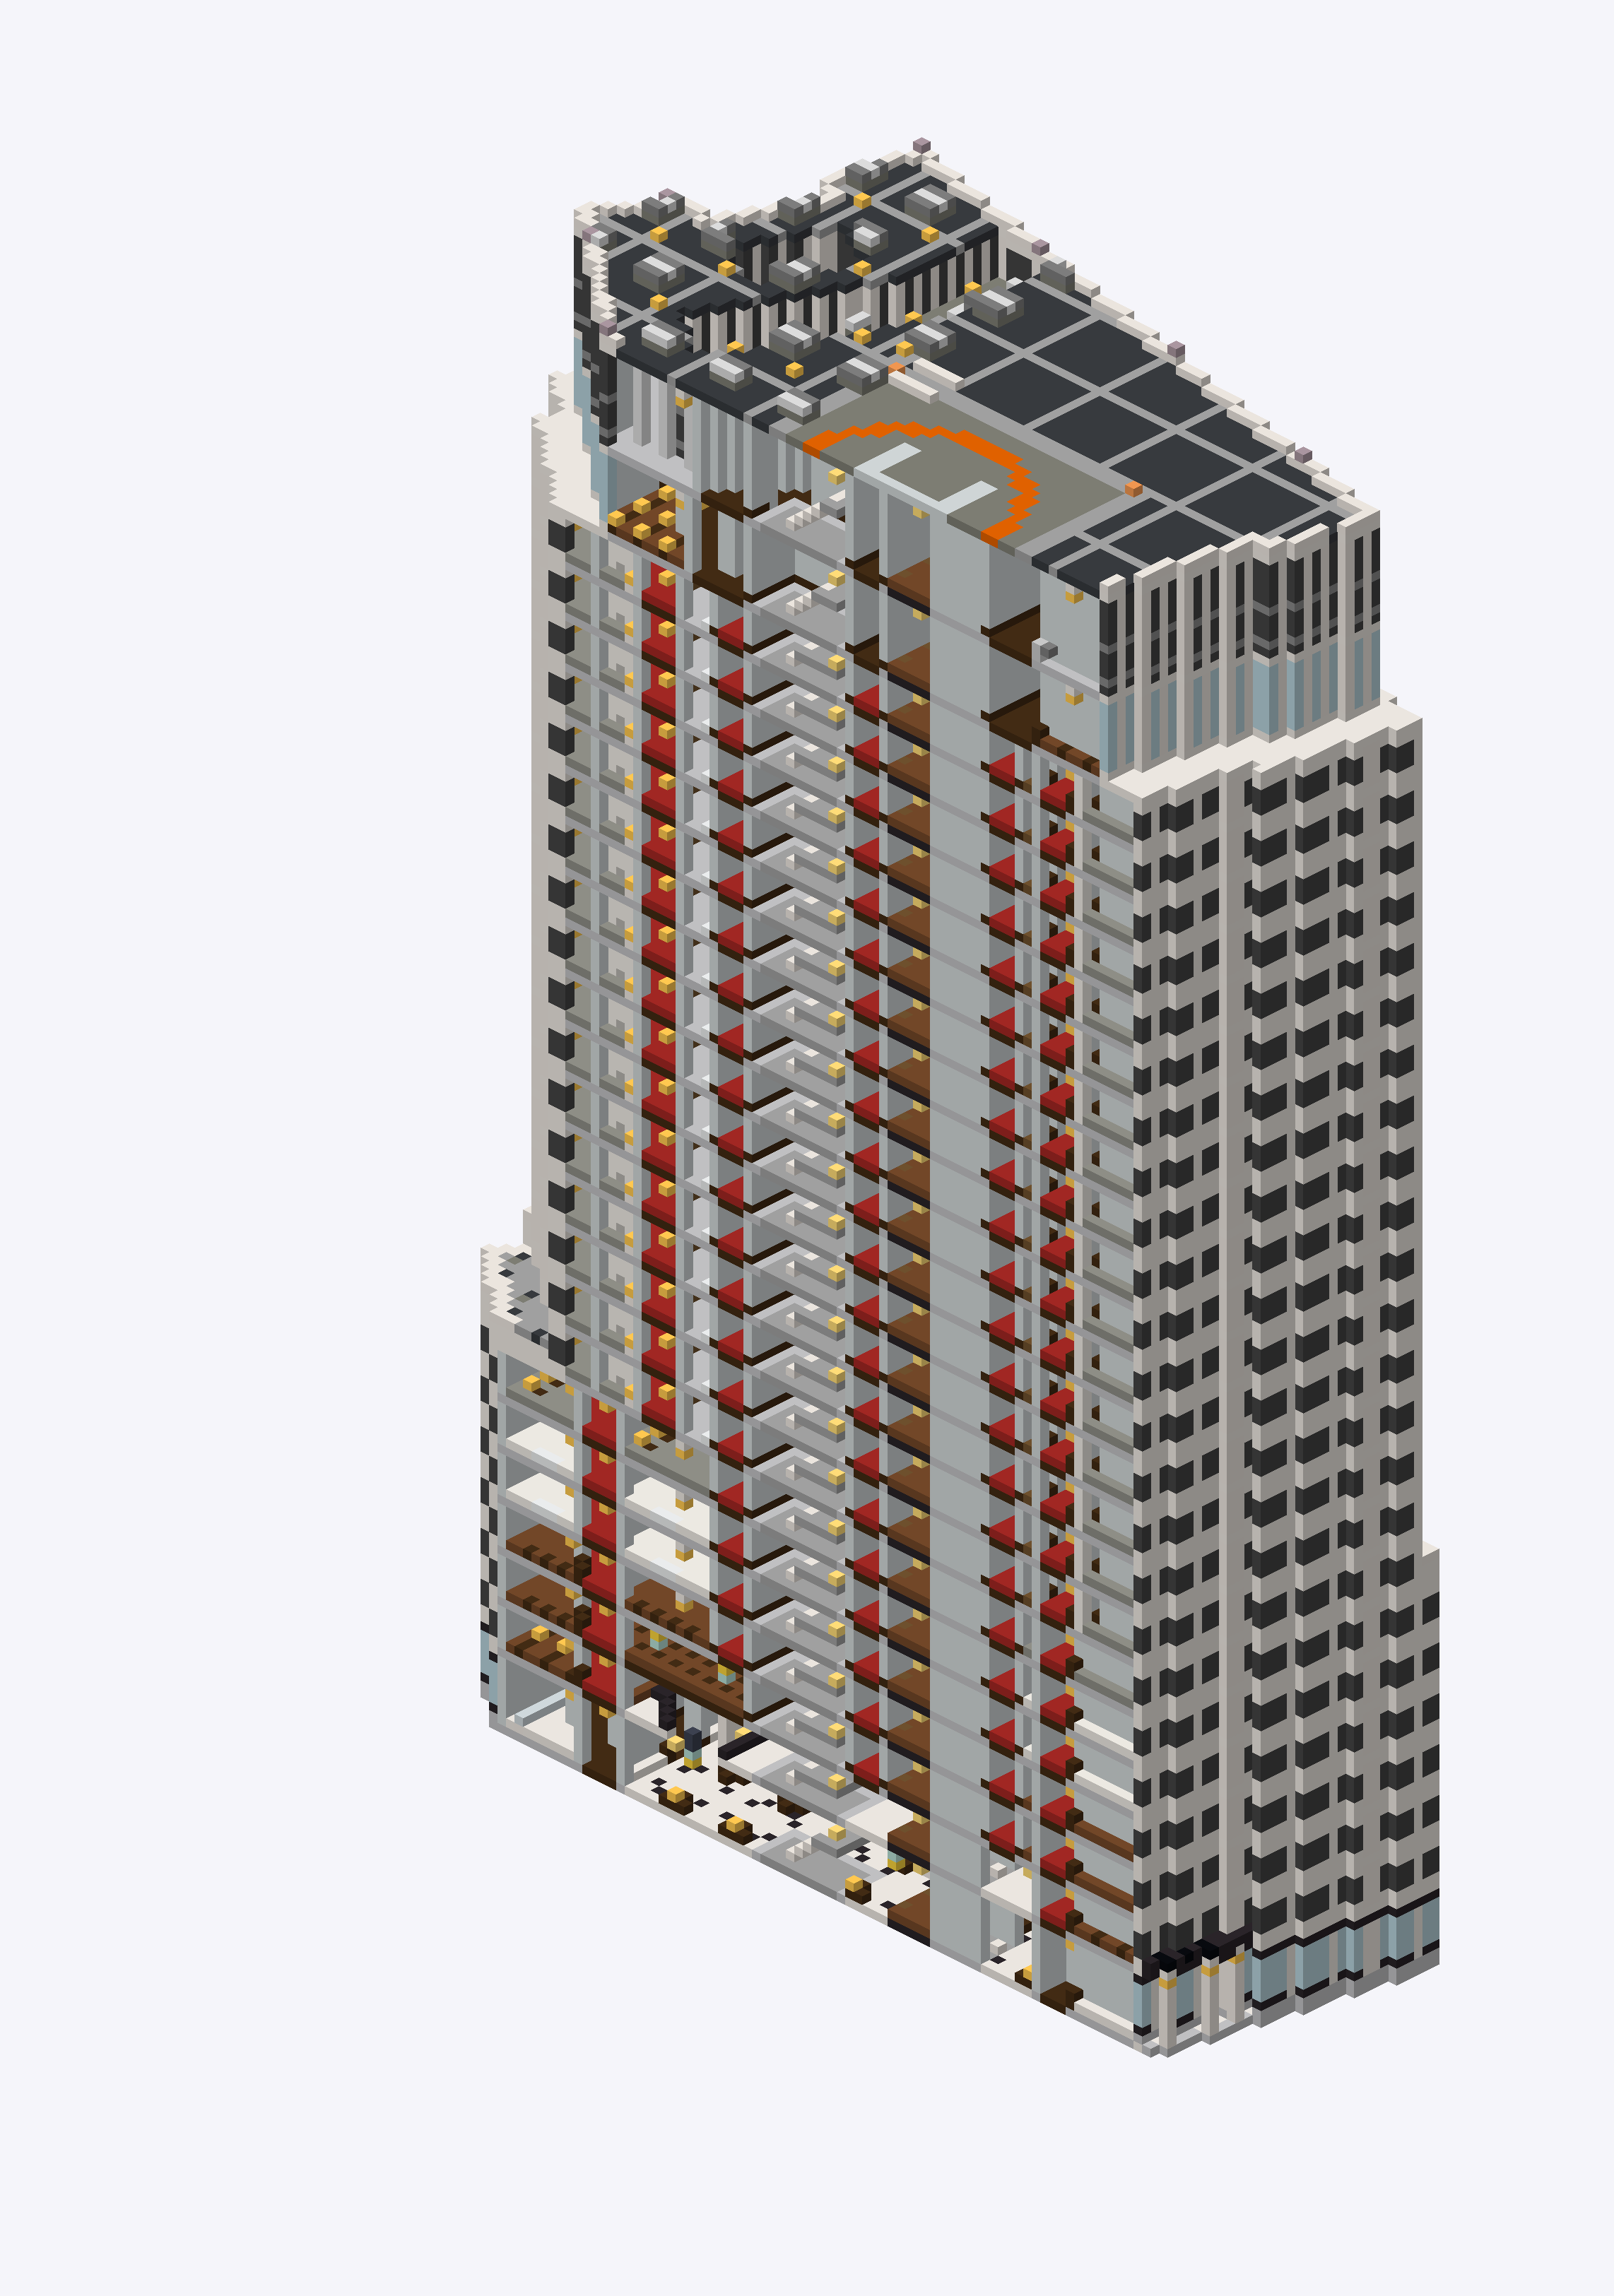
IMAI BLDG., four runs
This smaller building makes the effect of the reference package easier to inspect. Left to right: Opus with the newer survey and image inputs, an older Opus run without that expanded package, text-only DeepSeek, and the untrained Gemma 4 12B baseline. For these smaller buildings I initially gave them no input context other than basic footprint, descriptions and boundaries. I had higher expectations for Gemma 4 12B, but was pleasantly suprised by the output quality of opus and DeepSeek's latest flash model. DeepSeek's Flash model is especially notable given the permissive licensing allowing us to use it as a teacher for distilling knownledge/finetuning a Gemma 4 Student. The Deepseek model ran on 2 B300s utilizing NVFP4 optimizations with high and max thinking parameters. The throughput was up to 4k tokens/s on the B300s using batched queries. A Gemma 4 12B student could run with long context on a single RTX 5090.
The Chiyoda joint government building is a larger example. The render is shown with the aerial reference and facade strips supplied to the task. Its reported roof-height agreement is 1.00 under the two-block tolerance; that is a specific height check, not a score for the entire building's realism.
More builds and the scale problem
The build gallery contains 250 verifier-passing builds across 231 distinct tasks, including repeated attempts and open sites. It has filters for task type, size, and reasoning settings. The selection does not include every failed run, so it cannot establish an overall success rate. The Opus evaluation gallery contains the separate reference examples.
In-game tower view · 4×
For the larger Tokyo area, my planning estimate was 3.7 million buildings in a roughly 56 × 56 km window. That building count is an estimate. At about 60,000 generated tokens per building, it implies roughly 222 billion tokens before retries. The initial budget was around 88 days on 25 two-GPU nodes. A two-day scenario depended on reducing the token budget and achieving serving throughput we have not demonstrated. Which is quite impressive considering this is in the realm of a few hundred US dollars.
Generating a few convincing buildings and filling a city are different workloads. But I believe anyone with a few hundred dollars in cloud credits could achieve a fully modeled tokyo metro. From streets, to parks, to the subway systems.
Training a builder on one RTX 5090
The local training experiment is something I have queued up. The 11.91B-parameter language component of Gemma 4 12B completed a full forward pass, backward pass, and optimizer update at 32,768 tokens on one RTX 5090. Peak GPU allocation was 24.21 GiB; the three measured phases took 148.2 seconds in total.
That used substantial host-memory offload, gradient checkpointing, fused cross-entropy, and a streamed optimizer. It was full-parameter language-model training, with the image/audio embedders excluded. The 32k probe used synthetic tokens; a separate two-step supervised smoke run also saved a checkpoint. Neither result establishes a trained builder's quality yet.
The next useful test is whether a trained local model can produce buildings that hold up under the same visual and structural checks. Combining those persistent structures with a controllable neural renderer is the direction I want to pursue next.
Building references: 出典:国土交通省 Project PLATEAU / PLATEAU-Ortho, with OpenStreetMap context, © OpenStreetMap contributors. Reference cropping, voxel reconstruction, and visualizations are our modifications. PLATEAU's usage policy provides the attribution and reuse terms. The world-generation evidence records the metrics, scopes, and asset provenance.
The last demo changes Pokémon Emerald through a conversation. I ask the AI dungeon master to turn the NPCs, wild Pokémon, and trainer Pokémon into Zigzagoons while leaving the player human.
The agent inspects and edits game source, builds a replacement ROM, and uses playtest commands to check it. The recording shows edits reaching NPC handling, scripts, Pokémon creation, and battle code. After the build, it saves, swaps the cartridge, and reboots into the modified game. A nearby NPC is visibly a Zigzagoon, while the player remains human. Going into the shop all other NPCs are Zigzagoons. I've tried this with crazier prompts and it consistently works usign opus 5 and above tier models.
This is a working edit, build, test, and reload loop. The visible changes are compiled into the game, and the result includes a reboot. The build on my unplugged laptop takes minutes. I have compressed the middle eight minutes to fifteen seconds at 32×, with the opening and result left at normal speed.
That is the direction behind the title: an AI that can generate the environment, change a game's behavior, and render the result. These experiments do different parts of that today. Combining them into a reliable system is the next step.
Pokémon Emerald · AI code changes
Measurements and provenance. The experiment data contains the values behind the figures, test scope, and hashes of the source reports. The method notes distinguish the original NieR bridge, the later Ghostwire presenter, numerical reconstruction, and the paused Qwen experiment. The world-generation section has its own data, and the final video preserves the recorded ROM swap and reboot. Public API references come from NVIDIA and Qwen; reverse-engineering conclusions are my observations of the pinned binaries. The figures do not distribute their code or weights.